Friday, May 3, 2019

Atypicality Presentation Recap

Yesterday, I gave a presentation introducing the ideas of atypicality to the Monteleoni research group. These are the slides and handwritten notes. I plan to explore this idea further and write up better LaTeX notes, which I will then share as well. For now, the idea of atypicality centers around using two coders: one trained to perform best on typical data and one that is universal and not data specific. A sequence is atypical if its code length using the typical coder is longer than the universal coder, i.e. it is not favored by the typical coder indicating the information is somehow unique. 

An example of the usage of atypicality from their 2019 paper "Data Discovery and Anomaly Detection using Atypicality for Real-valued data."


I presented on Elyas Sabeti and Anders H⊘st-Madsen's 2016 paper titled "How interesting images are: An atypicality approach for social networks". I think there are lots of opportunities for development in the image space, e.g. using different representations of images maybe including deep learning, exploring what made those images interesting by training a supervised classifier on the resulting labels and exploring the learned features. I'm concerned that their atypicality could be keying on background features, a lot more investigation is needed to understand the details of this application. I also think the image application needs more rigorous validation. They could have tested against other kinds of images to see if they also were labeled as atypical. One idea that was suggested by a member of our group (Amit Rege) is using the atypicality idea in a down-stream application to speed up stochastic gradient descent by picking atypical examples to learn from. 

A list of atypicality papers, by Sabeti & H⊘st-Madsen:

Wednesday, April 24, 2019

Ulam–Warburton automaton inquiry: Part 1

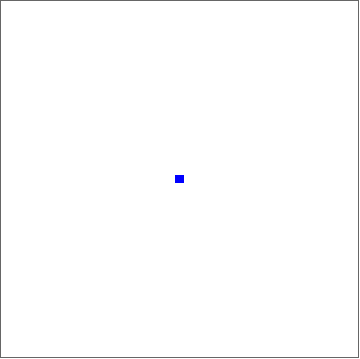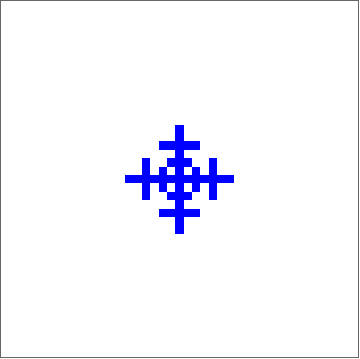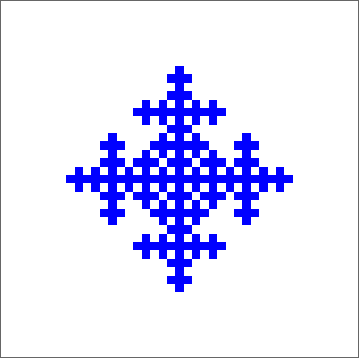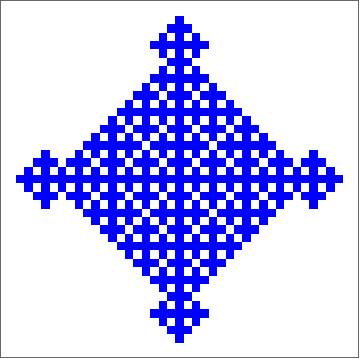
The Ulam-Warburton automaton is a simple growing pattern. See Wikipedia or this great Numberphile video for more information. For the more technical see this paper too.

Ulam-Warburton animation from Wikipedia
I was curious what you'd get under various other versions of it, using the same basic rule of "turn on cells with exactly one neighbor" but with a tweak. For example, what happens if you a cell turns off after being activated for a few cycles?


You get this beautiful modification. I plan to follow this up more and will make code available then (although it's insanely simple). I would be curious what statements you can make about the periodicity and the number of active cells at any time. 

For example, empirically it seems that the number of cells in a "dying" version is always upper bounded by the ageless and standard Ulam-Warburton Automaton. Now, prove that and derive formulas (or prove it's not possible) for a generalized version. 

Other ideas:
  • How does the total cell count formula change depending on the starting configuration, e.g. more than one active cell? 
  • Are there interesting stochastic versions? 
  • What happens when cells have a regeneration period, a time after they die before they can activate again? That models disease and other phenomena better maybe since resources/population has to restore before a new outbreak is successful. 
  • What if the age of a cell is a function of its position on the plane? 
  • Can we generalize to other grid types? 
  • How does this fit into other work? Has it already been done? 
This whole curiosity partially started because I wanted to assign a simple proof about Ulam-Warburton to my summer discrete math class. I also have an affinity for fractals, who doesn't?


Thursday, April 18, 2019

Denoising presentation

Slides [ppt or pdf] for a presentation I gave on denoising images. Noise2Self is amazing.

Check out this video from the related Noise2Void:

Wednesday, March 27, 2019

Training a denoising autoencoder with noisy data

How do you denoise images with an autoencoder if you don't have a clean version to train with? One option is to add more noise to your images! In this experiment, I trained an autoencoder with noisy MNIST data. I began with MNIST images on the bottom row, the noiseless versions. To simulate observational data, I added Gaussian noise to the images. In reality, we may never have access to these noiseless images. To train an autoencoder we need an input set with noise and output set without noise so the autoencoder can learn the denoising procedure. An autoencoder could potentially also learn the denoising procedure if we gave it extra noisy images as input and slightly denoised images as output. To simulate this, I added more Gaussian noise to the observations to arrive at the top row. Then, the top row is input and the second row is the output for training. When we want to denoise observations, we use this trained network with the observations as input and the denoised row as our output.

I am not sure how sensitive this is to an accurate noise model when adding noise or the amount of noise added. In the solar extreme ultraviolet setting, we suffer more from shot/Poisson noise than Gaussian noise. I am unsure how well this approach works under that setting.

An arguably more elegant approach to this problem is the "Blind Denoising Autoencoder" by Majumdar (2018). It does not require this noise addition or noiseless images.

Direction specific errors and granularity

In solar image segmentation, we identify many categories of structures on the Sun: coronal hole, filament, flare, active region, quiet sun, prominence. In our use case, some mistakes are more egregious than others. For example, mistaking a filament as a coronal hole is not too bad, no where close to as bad as calling it a flare. Assume we have a gold standard set for evaluation. (In reality, even this gold standard set may have errors, but we can ignore that for now.) It has a region labeled as filament. Ideally, we want our trained classifier to also call that filament. However, if it calls it quiet sun, we would be okay. Calling it coronal hole is also acceptable. Any other category is wrong, with the most egregious being if we call it outer space or flare. Now another portion of the Sun is labeled quiet sun in the gold standard. It is not okay for the classifier to then call it filament. In this way, it is acceptable to mistakenly label a filament as quiet sun but unacceptable to label quiet sun as anything else. The error depends on the direction of the mistake.

Similarly, in our current evaluation we evaluate errors on a pixel-by-pixel basis. In reality, we do not care about this granularity. We want coherent labeling. Small boundary disagreements are okay. We need a more robust evaluation metric.

TSS versus f1-measure


The above movie shows how accuracy, TSS, and f1-measure change under the assumption that a classifier has no false positives until it has classified all of a class correctly. The vertical grey line shows the actual percentage of the features having a given class versus the horizontal axis what percentage of the class is identified by the model. For example, if the true class percentage is 0.1 as shown below we see that an aggressive classifier, one that prefers creating false positives, is punished much less by accuracy and TSS than by the f1-measure. If the model to classified 20% of the examples as a true example, the accuracy and TSS is around 0.9 while the f1-measure drops to around 0.65. Selecting your metric is very important depending on if you prefer false positives or false negatives.


Thursday, March 21, 2019

Motivation for Denoising Solar images

I am beginning a project to denoise solar images. Here is a motivating example from March 8th, 2019. Off the limb of the Sun, faint features can be seen. These are hard to study without denoising. I am also interested in using dictionary learning for the denoising so that I can exploit the learned atoms as a mechanism for classifying the solar features too. Solar denoising relies on a Poisson noise model, different from the commonly used additive or impulse models.